

Introduction
This is an attempted summary on how “frontier” UX research teams are conducting research and structuring themselves in May 2026.
It is based on Deep Research from ChatGPT, Claude, and Copilot of the existing published literature on how UXR teams are using AI (sources at the end of the article), conversations I’ve personally had with other UX researchers and research leaders across industry, and some tea leaf reading.
It is meant to be practical. After reading this post, you should have a clearer path to move you and/or your research team closer to the frontier of UX research today. It doesn’t have all the answers. It raises questions. It is probably missing shout outs to a few new tools or authors (please LMK in the comments). It doesn’t capture what people are doing but haven’t posted about. It may be moot in a few months. We’ll see.
We’ll cover the mindsets, operating models, and infrastructure investments closer to the frontier. We’ll supplement all of that with call outs of old and emerging potential risks and some example roll-out plans if you’d like to move your team closer to the frontier in the way they operate. Each section has a checklist of actions to take if you’d like to put any of it into practice.
One quick note on terminology: I borrow the term “frontier” from the “frontier labs” to convey a sense of pushing what is possible given the new abilities we all inherited a few months ago (e.g. the AI coding agent inflection point). I like the term because it emphasizes feelings like being at the edge of what’s possible, redefining that edge as you go, having no real roadmap ahead of you, relying as much on intuition as pattern matching, and a newness we haven’t seen in our field in a generation.
Mindset
What does it mean to have a “frontier” or “AI-native” mindset for UX research?
The transformation from project-based approaches to AI-powered continuous intelligence is underway, but most teams are still bolting on tools rather than redesigning how research works. Maze’s 2026 survey of ~500 professionals shows 69% of researchers now use AI in at least some projects — up 19% year-over-year — while User Interviews reports 80% adoption. Yet the gap between “using AI tools” and “being AI-native” remains enormous. Only 11% of companies report significant financial impact from AI despite 72% adoption (McKinsey), and 95% of generative AI pilots fail to reach production (MIT). [21]
The bar is higher than adoption rates suggest. Deloitte warns against bolting agents onto operating models designed for humans — you amplify broken processes. McKinsey’s prescription is explicit: map workflows end-to-end, “agentify” high-impact parts, modernize your data stack for interoperability and governance, then build the operating model for supervision and orchestration. [22]
For our purposes, let’s describe AI-native UXR as:
A human-guided continuous discovery and evaluation system where AI and agents are default tools and participants in the research lifecycle. All data and tools are structured, connected, permissioned, and retrievable. The system architecture assumes they will be used by AI’s and supervised by humans. The system is a proactive participant in the research process, not a passive repository.
That description is operational, and is consistent with what “works” in the best recent UXR-adjacent examples:
AI works best when it’s plugged into your existing system of work, not when researchers are copy-pasting into chat windows. [23]
The current winning pattern is AI executes; humans decide what matters, especially in the interpretation and sense-making phases. [21]
Trust needs to be structural, not assumed. Transparency, control, consistency, and good failure support — and that applies to internal research copilots too. [24]
The through-line is thinking about it as a systems problem, not a tools problem. Buying Dovetail or shipping a Claude project won’t make you AI-native. Redesigning how evidence flows from collection through synthesis to decision — so that AI can participate at every step — will.
Operating models
Obviously mindset alone won’t make you AI-native. The right mindset needs to pair with a new operating model. The cross-functional playbooks converge on the same point: redesign the work so humans supervise and orchestrate while machines execute repeatable steps, with clear governance and decision rights. [50]
IBM’s February 2026 definition provides the clearest framework: AI-native means designed from the ground up with AI as a core component, not bolted on later. The test is whether removing the AI would make the system not just less efficient but fundamentally non-functional. Harvard Business School identifies a three-tier hierarchy — AI-embedded (adding tools), AI-first (AI as core capability), and AI-native (entire business model structured around AI). Most research teams today are at the embedded stage.
Across the December 2025– May 2026 corpus of publications on research with AI, the same moves repeat with different tooling and maturity. These are patterns you can design for and adopt.
Execution gets automated first, but teams hit a ceiling fast
AI is widely used for time sinks — transcription, summarization, clustering — and teams report speed and efficiency gains. But the same sources underline that human judgment stays essential for nuance, ethics, framing, and strategic recommendation. [25]
The single most adopted AI capability is analysis and synthesis. 88% of UX researchers identified AI-assisted analysis as the number-one trend for 2026 (Lyssna survey of 100 researchers). Teams report 60–80% reduction in qualitative analysis time.
Brad Orego (ex-Webflow, Auth0) published the most detailed practitioner framework through Great Question, breaking AI-assisted analysis into a six-step pipeline:
Transcription with structured output
Data reduction summarizing each participant’s responses
Open-to-closed coding where the LLM proposes 10–15 codes
Pattern identification attending only to the codes column
Theme development synthesizing patterns into narratives
Human-led insight generation for strategic implications
The key insight: “If you give an LLM a pile of transcripts and ask it to do analysis and synthesis, it’s unlikely you’ll get what you want back. Context management is absolutely crucial.”
Researcher Dominika Mazur’s hands-on experiment comparing human versus ChatGPT analysis found that LLMs are reliable at coding and synthesizing but humans consistently excel at generating non-obvious insights. The UXR Institute’s Leo Hoar reinforces this: analysis (breaking down) and synthesis (building up) cannot happen in the same gesture. Breaking tasks into discrete prompts reduces error propagation.
The most valuable cautionary tale comes from a financial services company documented by Hurix Digital. The team automated transcription and first-level analysis, but after three months discovered every synthesis report “sounded the same.” The AI eliminated nuance by forcing everything into templated buckets, and standout pain points went unnoticed. The recommended antidote: what Hurix calls the “80/20 Strategic Audit” — use AI for 80% of tactical synthesis, then reinvest saved time into deep-diving the 5–10% of outlier data points that AI miscategorizes as noise.
“Context engineering” replaces prompting
The more advanced workflows stop asking for generic “summaries” and instead feed strategic context — hypotheses, research plan, competitive context — and structure the task into stages that output artifacts that become inputs to the next stage. Atlassian’s example is explicit: providing hypotheses and research context changed the synthesis from “things users said” to “evidence mapped to what we’re testing.” Great Question makes the same point in analysis terms: dumping transcripts leads to generic output and hallucinated quotes; staged pipelines mitigate context-window and consistency limits. [26]
This mirrors a pattern from the startup world. Rather than writing detailed requirements that engineers implement, AI-native teams now specify the what and why, let AI plan the how, break work into small reviewable chunks, and have agents execute while humans verify. OpenAI’s four-person team shipped the Sora Android app in 28 days using this spec-driven development model. For research, the analog is specifying research objectives and letting AI generate study designs, discussion guides, and analysis frameworks — with researchers providing judgment at each checkpoint.
Evidence-backed output is now a core UX requirement
Tools and teams are shifting from “AI gives an answer” to “AI gives a claim linked to evidence.” Dovetail’s Explore positions this as the differentiator: summaries grounded in highlights, with traceability back to source moments. Atlassian’s workflow also emphasizes pulling quotes and patterns as evidence for each claim, then doing fast human critique passes. [27] BuildBetter’s May 2026 buyer’s guide goes further, arguing that citation transparency is now table-stakes: tools that can’t trace insights back to specific customer quotes with timestamps are considered untrustworthy for roadmap decisions. [58]
AI-moderated interviews scale collection
AI-moderated interviews represent what Great Question calls “the second wave” of AI in research tooling — after synthesis came collection. Maze, Dscout, Outset, Listen Labs, and HeyMarvin all now offer AI moderation at scale. The UXR Guild frames it well: think of AI moderation not as traditional moderation but as “a smarter survey that’s able to ask follow-up questions and do thematic analysis.” Microsoft’s Copilot research team has integrated Outset as a core workflow tool, reporting that “access to their tool has transformed the way we work and the speed and depth of how we are able to understand and build for our users.”
Multi-source synthesis on top of a research repo
The modern target for research artifacts isn’t a place to store decks. It’s a system where interview data, notes, plans, and adjacent context can be searched and synthesized together — including across channels (interviews, support tickets, sales calls, reviews). Dovetail calls this “spotting recurring issues across channels,” and Atlassian frames the real question as connecting research evidence to strategic context fast enough to drive decisions. [27]
TuringPost’s “Org Age of AI” series articulates the principle well: AI-native organizations must make their knowledge accessible to machines — defaulting to plain text or Markdown, choosing tools by visibility and portability, and treating context management as part of management. “If context lives only in people’s heads, it does not really belong to the company yet.” That has direct implications for how research repositories need to work.
Democratization accelerates, and enablement becomes existential
Maze’s data shows research demand is rising and spreading: PMs, marketers, and others are running studies. But only about half have research libraries, repositories, or training. Enablement means teaching the thinking, not tool clicks. AI makes it easier to do research-like activity, which makes quality drift more likely unless you build guardrails. [28]
If non-researchers are running studies, treat enablement like a product with SLAs: templates, training, office hours, and repository expectations. Publish quality guardrails that are easy to comply with and hard to bypass, and build agents that help people comply (e.g., auto-redaction, metadata suggestions). [52]
The coding model leap changed what UXR can build
Post-December 2025, agentic coding tools are full-context partners that operate across repositories, docs, and CI and can execute multi-step workflows. That matters because it drops the cost of building internal research infrastructure: connectors, ingestion pipelines, redaction scripts, RAG indexes, evaluation harnesses, and “insights to ticket” automations. [29]
BuildBetter’s workflow demonstrates the most radical departure from traditional product development. Their team ships features daily without Figma mockups, Linear tickets, or traditional specs. Customer signals flow directly to AI-assisted specifications with real quotes, then to AI-planned tasks and agent-assisted code. Their insight: “When AI agents can hold the full context from customer pain to code execution, the artifacts in between become optional.” For research operations, this suggests a future where the boundary between research finding and product action collapses.
This also means ResearchOps turns into “research systems engineering.” Start low-risk (scheduling, recruitment, incentives), layer AI where oversight is easy, integrate via APIs and webhooks, establish governance rules, and measure ROI. [19] Formalize a small “research engineering” function — could be fractional — that owns ingestion, connectors, redaction, indexing, and evaluation harnesses, using coding agents to ship internal tools faster. [53]
Governance moves from policy doc to daily UX
Once you let agents touch real systems, permissions, audit logs, prompt-injection risk, and least-privilege design stop being security-team trivia and become part of the product UX. Atlassian is unusually explicit: MCP enables powerful workflows but creates structural risks, and LLMs are vulnerable to prompt injection and tool poisoning — so require least privilege and confirmations for high-impact actions. [30]
Operating model to-do list
Adopt the six-step AI analysis pipeline (transcription → data reduction → coding → pattern identification → theme development → insight generation) with clear human checkpoints at steps 4 and 6.
Implement the 80/20 Strategic Audit — AI handles tactical synthesis, researchers deep-dive outlier data.
Define an explicit “analysis pipeline” with artifacts and human sign-offs at each stage: raw transcript → structured transcript → utterance summaries/first-pass tags → candidate themes with evidence links → insight briefs mapped to hypotheses.
Pilot AI-moderated interviews for one low-stakes study to learn the moderation-quality tradeoffs firsthand.
Publish quality guardrails for non-researchers running studies, and build agents that help people comply.
Identify one “research engineering” project a coding agent could ship in a week (e.g., auto-redaction, metadata suggestions, a screener generator).
Green shoots
These are the new experiments people are discussing. Not quite part of the core Operating Model yet. Relatively uncommon, mostly unproven, but potentially high-leverage if you can execute.
Research plumbing via MCP vs. bespoke integrations
A small but important shift: instead of building one-off connectors, teams use the Model Context Protocol to let AI tools securely access research repositories and other systems with user-scoped permissions. Dovetail’s MCP server explicitly frames this as turning an assistant into an “informed teammate” that can query data and find evidence without copy-paste. Atlassian is pushing MCP connectors as the path to live “sources of truth” and even writeback actions. [31]
MCP has become the critical integration layer more broadly. Anthropic’s protocol, now donated to the Linux Foundation, enables AI agents to connect to external tools — Figma, Linear, PostHog, Salesforce, Zendesk. For research, MCP means AI agents that can pull from CRM data, support tickets, product analytics, and research repositories simultaneously, eliminating the manual data-gathering that consumes researcher time.
The risk: MCP expands your attack surface. Treat every connector like production code with threat modeling, not “an integration someone enabled.” [32]
Research-knowledge agents that activate the repo
A still-rare practice: treating the repository as something that needs ongoing activation. Agents that ingest work, enforce metadata and PII rules, connect research to planning artifacts via citations, and publish routine “what changed?” reporting. This solves the chicken-and-egg adoption problem of repositories. [37]
Agentic delivery — where AI agents proactively push relevant insights to stakeholders via Slack or Teams when they detect relevant patterns — eliminates the researcher-as-messenger bottleneck. Dovetail is building this capability. The shift from “researchers push findings” to “the system delivers intelligence” is structural.
AI-assisted qualitative analysis that preserves reflexivity
Most AI-qual workflows are still “summarize and cluster.” The more methodologically serious exception is using AI inside a reflexive analytic method with explicit ethics and researcher subjectivity — not pretending analysis is mechanical. A 2026 methods paper walks through using ChatGPT within Braun & Clarke’s reflexive thematic analysis phases and argues against universalizing a single TA approach when adding AI. [33]
The risk: if you don’t declare your analytic stance and audit AI’s role, you get fast slop — themes that sound plausible but aren’t methodologically coherent. [34]
UXR owns evals of model response quality
AI model output quality has typically been assessed via “machine” and “human” evals, which correspond to automated benchmark tasks run completely through code and asking humans trained specifically for evaluation tasks what they think of model outputs.
However, these tend to provide weak signal over time as machine evals become saturated - i.e. models can easily get near 100% - and human (aka expert) evals are fairly artificial - e.g. asking someone who is not a particular demographic or in a particular mindset to imagine they are.
UX researchers at companies including Microsoft and Meta are adding a third kind of eval - user evals. These are evaluations where users have more natural, multi-turn conversations with AI models for a specific use case (aka Intent). The participants then rate the model outputs on a set of dimensions, typically 5-8, that have been determined to drive model quality perceptions based on previous, qualitative research. These assessments are then used to improve model quality, either version or version, or in a competitive framing with other AI models.
Early reports show these User Evaluations to be highly valuable to model improvements, providing high additional signal on top of machine and human evals.
Synthetic users as heuristic evaluators
48% of researchers see synthetic users as an impactful 2026 trend (Lyssna), and a Stanford study showed synthetic agents can mimic human responses with up to 85% accuracy. But academic criticism is mounting. A systematic review of 182 studies (March 2026) identified four fundamental issues: cognitive misalignments, distortions, misleading believability, and overfitting/contamination. A Cambridge University study found that 48% of coefficients estimated from AI responses were significantly different from human counterparts, and among those, the sign of the effect flipped 32% of the time — meaning AI sometimes completely reversed the direction of relationships.
The practical failures are vivid. Synthetic design engineers gave “textbook answers” about sustainability’s importance; real engineers said “sustainability matters, but not when we can’t get the parts we need for months.” Synthetic users enthusiastically described forum participation while real users avoided forums entirely, calling them “contrived.” 42.75% of market researchers are “not excited” about synthetic respondents (Rival Group 2026 Trends Report).
The emerging consensus is a sequenced approach: run synthetic users first to cover the problem space broadly and refine questions, then spend the organic research budget on the depth only real humans can provide. NN/g warns that synthetic insights should be treated exclusively as hypotheses, never as validated findings.
The risk: validity and fairness can break in non-obvious ways. A 2026 agent-evaluation study finds LLM-simulated users are not robust proxies for real humans — miscalibration, demographic disparities, different conversational artifacts. Synthetic “research” can quietly bake in the wrong world model. [36]
The “Pattern Skeptic” role
This reframes the researcher as a professional critic of AI-generated insights rather than a producer of insights. Rather than building affinity diagrams, researchers spend their time vetting, challenging, and contextualizing AI outputs — a fundamentally different skill set.
Green Shoots to-do list
Evaluate MCP integrations to connect your research repository with product analytics, CRM, and support systems. Start with one read-only connector.
If your team is researching agentic AI products, pilot an intent-mapping exercise in place of a standard journey map for one study, and add a trust-over-time measure (diary study or experience sampling) to at least one longitudinal evaluation.
If you run AI-assisted qualitative analysis, declare your analytic stance explicitly and audit AI’s role at each stage.
Experiment with the “Pattern Skeptic” model on your next synthesis: have AI generate the themes, then have a researcher spend their time challenging and contextualizing rather than building from scratch.
Sequence synthetic users before real participants for one upcoming study — use them for hypothesis generation and question refinement, never for validation.
Infrastructure
If the mindset is shared and the operating model has shifted, all of that needs to be supported through the right infrastructure. The emerging blueprint is to optimize for compounding knowledge and decision integration, not for “faster deliverables.”
Think of the stack in three layers: evidence layer → intelligence layer → decision/action layer. That’s the common structure behind the strongest examples (Atlassian’s end-to-end workflow + Dovetail’s evidence-backed discovery). [39]
Evidence layer
You need a canonical place where raw evidence lives with durable metadata: transcripts, highlights, clips, notes, artifacts, and the research plan/hypotheses that explain why the study existed. Atlassian’s case explicitly shows why: synthesis got better when the agent had hypotheses and plans, not just transcripts. [40]
Minimum investments:
A shared research repository that supports traceability from claim → source evidence (highlights/clips), not just doc storage. [41]
A team-wide taxonomy and metadata model (what the study was for, who it’s about, what decisions it supports). The “metadata pain” is real; offloading it is exactly where agents can help. [42]
Explicit handling for privacy, consent, and retention. Consent tracking, deletion workflows, and auditability have to be built into the workflow, not stapled on later. [43]
Intake becomes “decision engineering,” not “request triage.” Every inbound request gets converted into: the decision, the confidence bar, the cheapest evidence that moves confidence, and the “who will act.” This aligns with Maze’s framing that UXR value is in framing sharper questions and making recommendations, not running studies for their own sake. [21]
Process change: a lightweight intake template + an “intake agent” that drafts the decision map and flags risks/unknowns, then a human researcher approves it.
Research plans become living artifacts that agents can use. If you want agents to synthesize well, they need the plan, hypotheses, and constraint set. [46]
Process change: “no plan, no study” (even for fast work). The plan can be brief, but it must exist in the evidence layer.
Intelligence layer
This is the pipeline preserving evidence of governance and fighting slop.
Core capabilities:
Retrieval and Q&A over the repository with citations and a “not found” posture, not guessy summaries. Evidence-grounded summaries are the confidence mechanism. [44]
Structured analysis/synthesis pipelines (“context engineered”), producing intermediate artifacts you can review: utterance summaries → candidate codes → themes → insight briefs. [45]
Evaluation loops where humans critique and iterate quickly. Atlassian reports a key benefit: people felt freer to be hard on the draft because it wasn’t a human author; iteration speed kept momentum. [46]
Decision and action layer
AI-native fails if insights don’t land in the tools where decisions happen.
Core capabilities:
Connect the research system to the broader system of work — search and retrieval across docs and tools, and eventually safe writeback. Permissions and data-policy alignment are non-negotiable.
Use MCP wherever possible to avoid bespoke glue code and to standardize how assistants access tools and data.
Hard security constraints: least privilege, trusted clients/servers, human confirmation for destructive actions, and audit-log monitoring.
Make it social
A16z’s Fareed Mosavat identified the critical gap: “Right now, most AI tools are built for one human and one model in a private workspace. Incredibly powerful, but currently optimized for individuals. Almost none of it is shared, aligned, or contextualized across a team.” This multi-player AI gap is the infrastructure challenge for research teams — how to move from individual researchers using ChatGPT in private sessions to shared, governed, team-wide AI systems with persistent context.
For UX research specifically, the AI-native operating model means: research questions queryable from past studies via conversational interface (not PDF searches), continuous feedback channels that AI processes and surfaces automatically, AI agents that proactively deliver relevant insights to Slack or Teams when they detect patterns, and prompt libraries for common research operations that any team member can execute with quality guardrails.
Everything is visible and proactively shared among all humans and AI’s using the system.
Infrastructure to-do list
Build (or choose) a shared, AI-powered research repository that centralizes past findings, transcripts, and customer signals into a queryable knowledge base.
Implement a team-wide prompt library for common research operations — screener generation, discussion guide drafting, thematic coding templates — version-controlled and shared.
Establish data governance policies covering AI model access to participant data, output validation requirements, and labeling standards for AI-generated versus human-generated insights.
Create a lightweight intake template that converts every inbound ask into: the decision, the confidence bar, the cheapest evidence that moves confidence, and the “who will act.”
Enforce “no plan, no study” — even for fast work, the plan must exist in the evidence layer so agents can use it.
Rollout
So if you’re still with us, you’re hopefully inspired by at least some of this. Here’s how to sequence it.
A sample rollout plan
First month: Choose the canonical evidence system. Define the minimum metadata header. Turn on automated transcription + structured export. Establish privacy/retention rules and deletion workflows. [54]
Next two months: Implement the analysis pipeline (staged artifacts + evidence links). Ship “ask-the-repo” with citations. Pilot MCP-based access for a small group. Add logging and least-privilege controls. [55]
Following quarter: Integrate outputs into planning and execution tools. Add reporting/alerting agents that push decision-relevant updates. Expand enablement for non-researchers with guardrails and coaching. [56]
Or if you prefer, here is a table of actions sorted by priority:
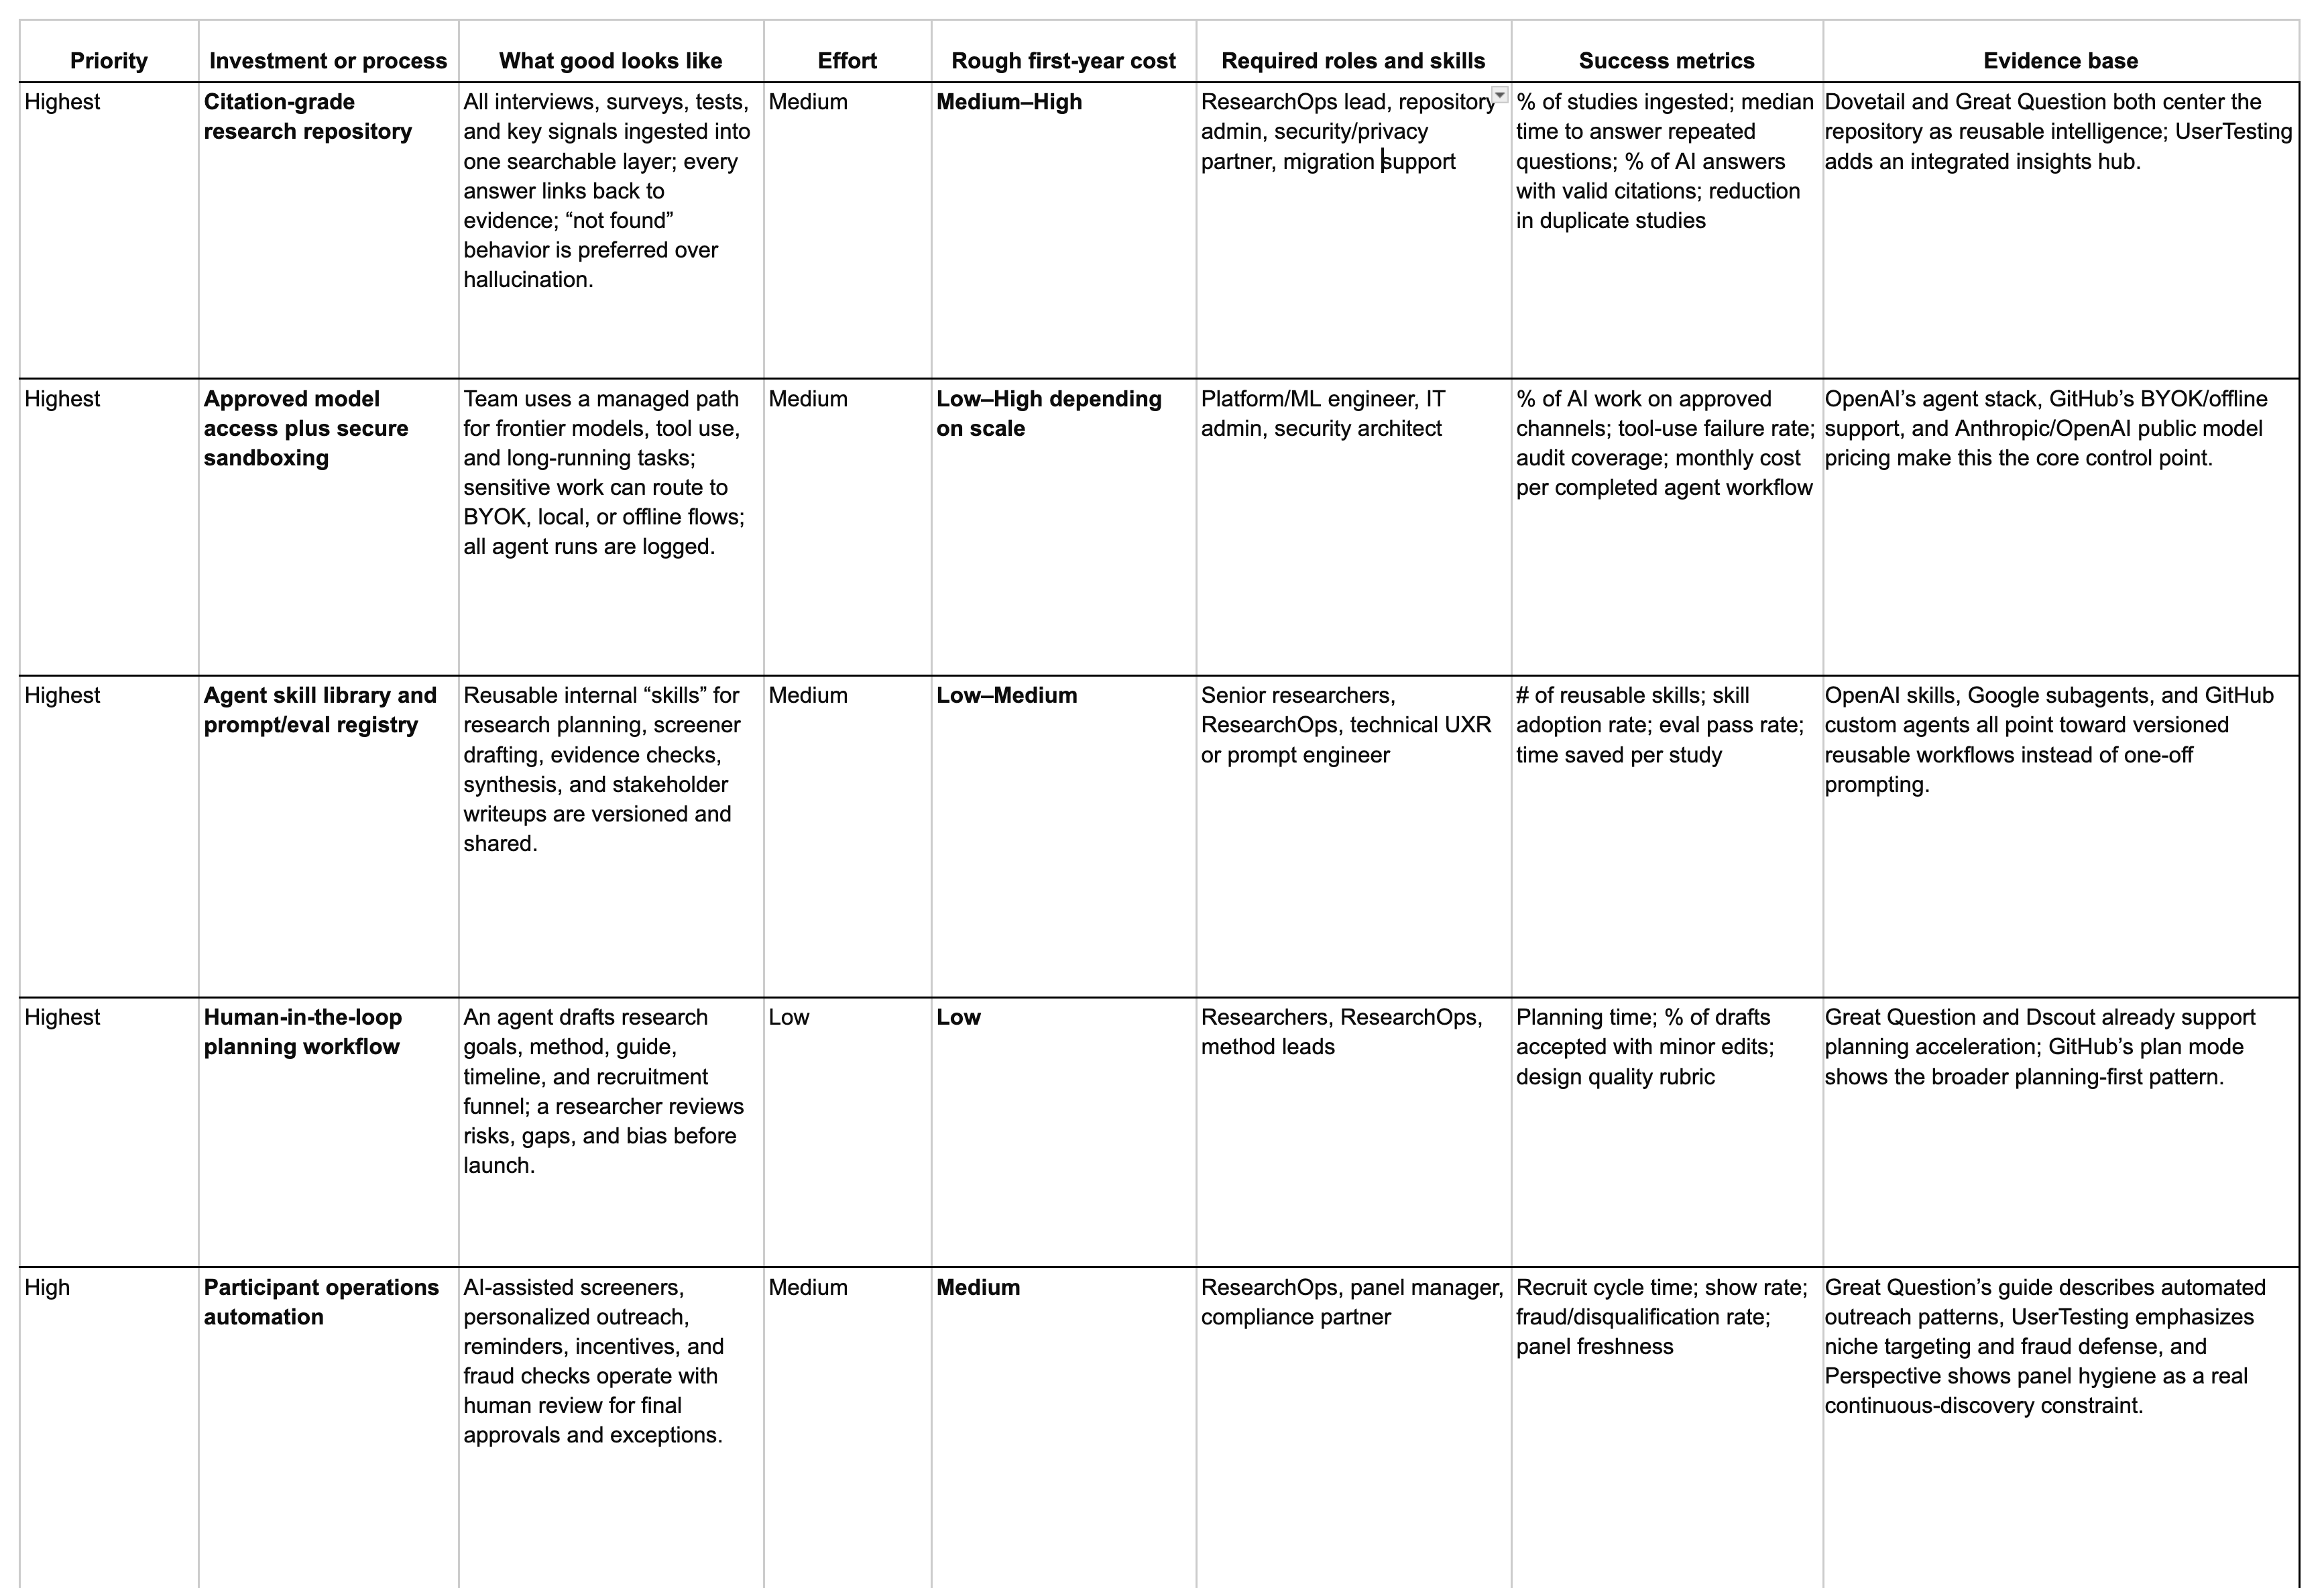
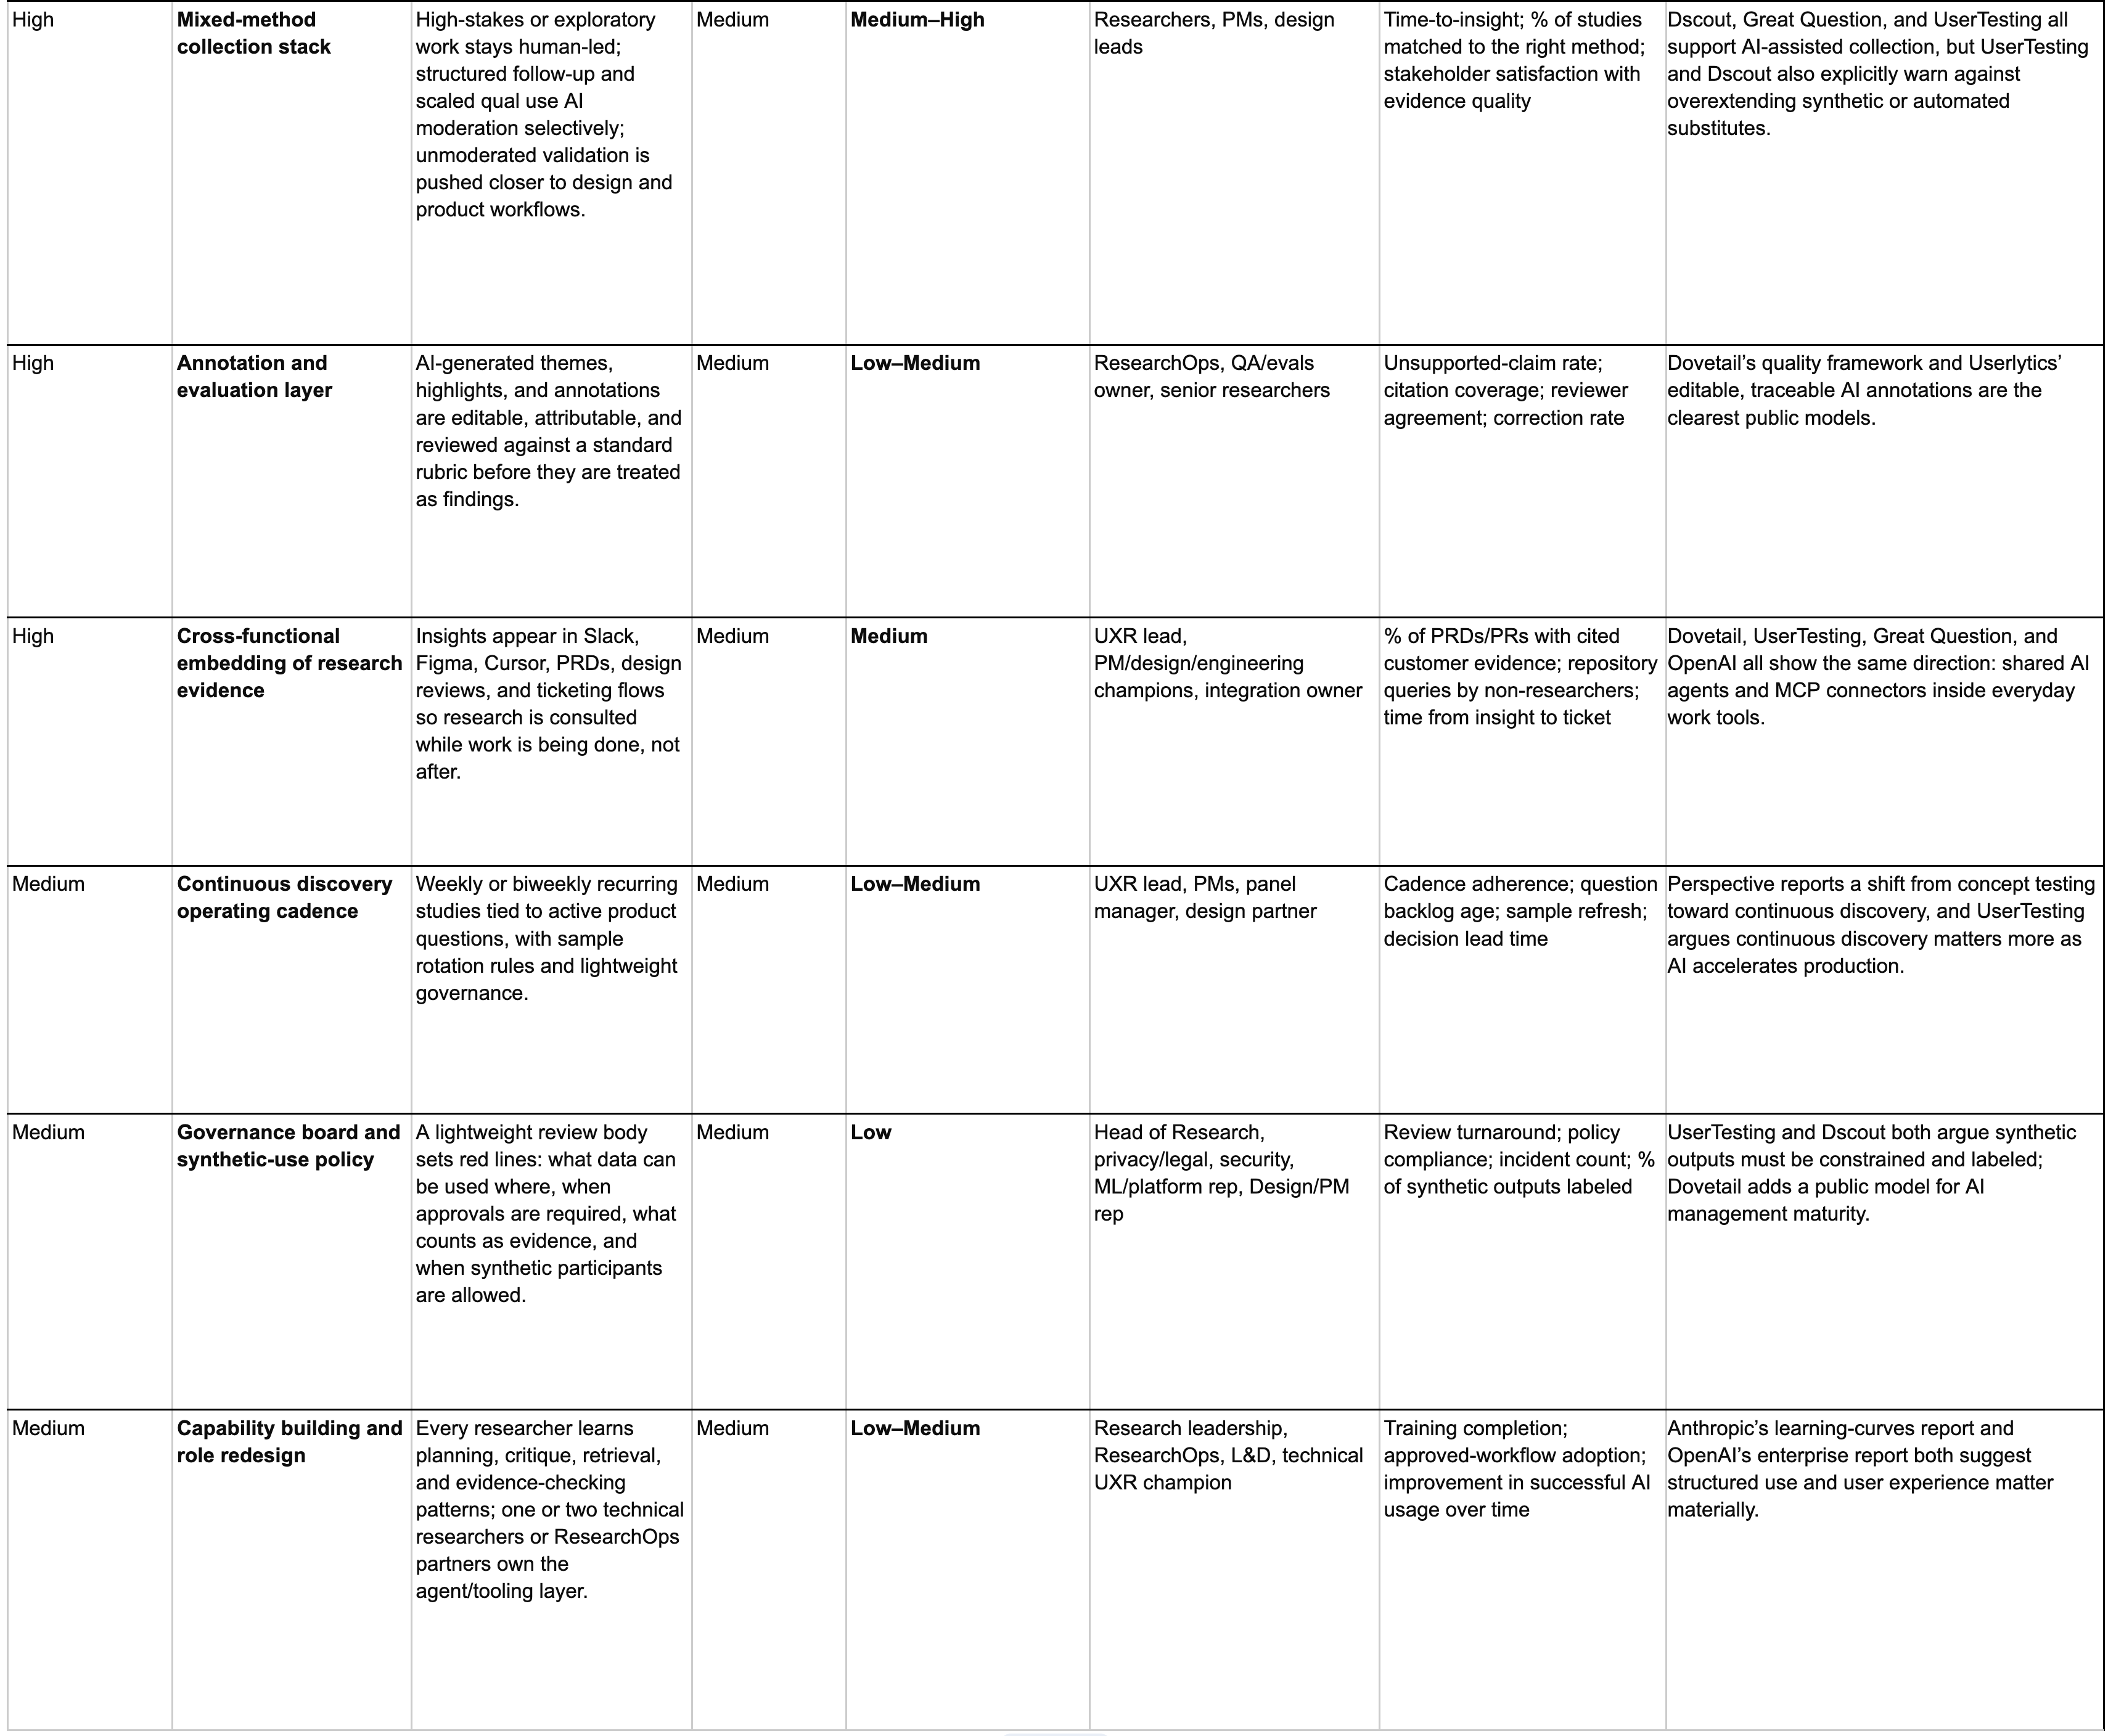
(You can’t have tables in Substack articles but just screenshot and give it to an AI to turn it into a text checklist.)
Risks, traps, and dead ends
You already knew this wasn’t all for free. Like with any platform shift, there are potential risks, traps, and dead ends to look out for.
Focusing only on getting more productive at the existing things
Don’t start by making researchers “more productive” at producing decks. Start by making research knowledge compound and by wiring it into decisions with traceable evidence. That’s the difference between a faster content factory and an AI-native learning system. [57]
Becoming accidental behaviorists
NN/g found that AI tools “are not currently capable of truly observing or analyzing usability testing” — they analyze transcripts, not actual behavior, and “people often say one thing but do another.” NN/g’s March 2026 article warned that many research tools were “not built by expert researchers” and now make “significant methodological mistakes” at AI scale, producing “flawed research presented with confidence.”
We can focus so much on agents observing behaviors we miss the goals, beliefs, motivations, and aspirations that underpin the behaviors.
Getting AI brain fried
“AI brain fry” affects 14% of AI-intensive workers (BCG/HBR, March 2026). Symptoms include mental fog, difficulty focusing, and slower decision-making. Using three or more AI tools simultaneously causes productivity to plummet. A Workday survey found that employees lost 40% of AI efficiency gains correcting, rewriting, editing, or fact-checking AI output.
NN/g declared 2026 “the year of AI fatigue.” UX professionals report exhaustion from being told they’ll be replaced by vibe coding, sold tools that don’t integrate into real workflows, forced to explain why automating critical decisions is risky, and pressured to ship AI features because competitors did. This fatigue is organizational, not individual — and ignoring it undermines adoption.
Ethical and RAI blind spots
A Yale study (PNAS Nexus, March 2026) found AI chatbots subtly influence users’ social and political opinions through latent biases even when not prompted to persuade. AI speech evaluation tools show systematic bias against neurodivergent speakers and second-language English speakers (UC Berkeley). The EU AI Act introduces penalties of up to €35 million or 7% of worldwide revenue for non-compliance. Research teams handling participant data through AI systems need explicit data governance policies, particularly regarding whether AI models are trained on proprietary research data.
All of the leading AI’s are improving at rapid rates but we still need to be careful.
Risks, traps, and dead-ends to-do list
Invest in AI literacy training focused on context management, prompt engineering for qualitative research, and output validation.
Have the team explicitly choose a collaboration model (Apprentice, Associate, or Parallel) for each project based on stakes and complexity — don’t default to one.
Identify one researcher who wants to experiment with vibe coding and give them space to build a small internal tool (a screener generator, a consent tracker, a synthesis dashboard).
Expect the team to stay about the same size or become smaller, more senior, and more strategic over the next 2–3 years — with increased influence per researcher.
Conclusion
If this snapshot is useful, it should give you two things: a clear picture of where the frontier is, and a set of concrete steps to get closer to it.
The core argument is simple. AI-native research is not about buying the right tools. It is about redesigning how evidence flows — from collection through synthesis to decision — so that machine intelligence can participate at every step. That requires structured data, connected systems, explicit governance, and a team that knows when to lead and when to let the machine draft.
Three things will separate teams that make this transition from those that don’t. First, treating your research repository as living infrastructure, not a filing cabinet — queryable, cited, and wired into the tools where decisions happen. Second, building shared AI systems (prompt libraries, analysis pipelines, MCP integrations) instead of letting each researcher work in a private chat window. Third, investing in judgment: the 80/20 audit, the Pattern Skeptic role, the human checkpoints in the analysis pipeline — the places where researchers add what AI cannot.
The pace of change here is real. The coding model inflection point in December 2025 didn’t just change what researchers can write — it changed what they can build. That means the cost of internal research infrastructure is dropping fast, and the teams that move first will compound their advantage.
Given the pace of development, it may make sense to update this quarterly (or monthly?!?).
Sources
Primary sources (numbered inline citations)
[19] [43] [54] Ethnio — The Future of UX Research Automation: https://ethn.io/blog/The_future_of_UX_research_automation_how_ops_teams_scale_insights_without_sacrificing_quality
[21] [25] [28] Maze — The Future of User Research Report 2026: https://maze.co/blog/future-user-research-2026/ and https://maze.co/resources/user-research-report/
[22] Deloitte — Operating Models for Humans & AI Agents: https://www.deloitte.com/us/en/insights/topics/talent/operating-models-for-humans-ai-agents.html
[23] [26] [39] [40] [46] Atlassian — Research with Rovo Dev: https://www.atlassian.com/blog/artificial-intelligence/research-with-rovo-dev
[24] Nielsen Norman Group — State of UX 2026: https://www.nngroup.com/articles/state-of-ux-2026/
[27] [38] [41] [44] [57] Dovetail — Introducing Explore: https://dovetail.com/blog/introducing-explore-a-new-way-to-dive-into-customer-knowledge/
[29] [53] LeadDev — Best AI Coding Assistants: https://leaddev.com/ai/best-ai-coding-assistants
[30] [32] [49] Atlassian MCP Server (GitHub): https://github.com/atlassian/atlassian-mcp-server
[31] Dovetail MCP Server: https://docs.dovetail.com/integrations/mcp-server
[33] [34] SAGE Journals — AI in Reflexive Thematic Analysis: https://journals.sagepub.com/doi/10.1177/16094069261425173
[35] Nielsen Norman Group — Digital Twins: https://www.nngroup.com/articles/digital-twins/
[36] ArXiv — LLM-Simulated Users Evaluation: https://arxiv.org/html/2601.17087v1
[37] [42] [52] [56] Medium/Integrating Research — AI Agent Ideas in Research Knowledge Management: https://medium.com/integrating-research/ai-agent-ideas-in-research-knowledge-management-cca2f92d2dd0
[45] [51] [55] Great Question — AI Analysis & Synthesis Pipeline: https://greatquestion.co/ux-research/ai-analysis-synthesis
[47] Atlassian — Rovo MCP Connector for ChatGPT: https://www.atlassian.com/blog/announcements/atlassian-rovo-mcp-connector-chatgpt
[48] Model Context Protocol Specification: https://modelcontextprotocol.io/specification/2025-11-25
[50] McKinsey — Building Foundations for Agentic AI at Scale: https://www.mckinsey.com/capabilities/mckinsey-technology/our-insights/building-the-foundations-for-agentic-ai-at-scale
[58] BuildBetter — AI-Powered User Research Tools: The 2026 Buyer’s Guide (May 2026): https://blog.buildbetter.ai/ai-powered-user-research-tools-the-2026-buyers-guide/
[59] Built In — Why UX Research Powers Better Agentic AI (April 14, 2026): https://builtin.com/articles/ux-research-better-agentic-ai
[60] Akraya — Do Users Trust Your AI Agent? A UX Research Framework for Agentic Experiences (May 1, 2026): https://www.akraya.com/blog/do-users-trust-your-ai-agent-a-ux-research-framework-for-agentic-experiences
[61] InfoWorld / Priyanka Kuvalekar (Microsoft) — Building Enterprise Voice AI Agents: A UX Approach (May 13, 2026): https://www.infoworld.com/article/4153289/building-enterprise-voice-ai-agents-a-ux-approach.html
Additional sources by category
UXR Industry Reports & Trend Pieces: Lyssna — UX Research Trends 2026; Akraya — UX Research 2026: Trends to Watch Out For; UX Studio — What’s Next for UX Research?; UX Tigers — 18 Predictions for 2026; NN/g — Accelerating Research with AI; NN/g — The Methodological Problems Hiding in Your Research Tools; NN/g — A Research Agenda for Generative AI in UX; LogRocket — 3 UX Research Trends 2026; UserTesting — AI in UX Research: 2026 Trends and Impact.
Practitioner Frameworks: Great Question — Complete 2026 Guide; UXR Institute (Leo Hoar) — AI-Supported Analysis Workflow; Dominika Mazur (Medium) — AI vs. Human Data Duel; Nishita Shah (Medium) — AI Is Rewriting the Job Description; Connor Joyce (UX Collective) — Same, but New: UX Research in the Age of LLMs; Articos — How AI Is Changing UX Research; Parallelhq — AI for UX Research; UX Design Institute — Top AI Tools for User Research.
Tools & Platforms: Dovetail (AI Features, AWS case study); Maze (AI Moderator); Outset.ai; Listen Labs; HeyMarvin; Koji; Synthetic Users; Dscout; UserTesting (Feedback Engine, CTO appointment, Responsible AI); BuildBetter (AI Tools for UX Research 2026, Vibe Coding for Product Teams, 2026 Buyer’s Guide); Conveo — 15 Best AI Tools for UX Research (May 2026).
Synthetic Users Research: Skimle — Synthetic Respondents: Promise, Pitfalls, and When to Use; IxDF — AI-Generated Synthetic Users vs. Personas; Articos — Synthetic Users Guide; AI CMO — Synthetic Users Review 2026; Sciety — Systematic Literature Review of LLM-Generated Synthetic Participants.
Enterprise & Governance: Hurix Digital — AI in UX Research: Enterprise Gains, Risks & Governance.
AI-Native Organizations & Startup Patterns: Greylock Partners — Rise of AI-Native User Research; Anu Joseph (Medium) — AI-Native Engineering; TuringPost (Substack) — How to Build an AI-Native Startup; Speedrun (Substack) — 14 Big Ideas for 2026; HBS Online — How to Architect an AI-Native Business; IBM — What Is AI Native?; HyperScale AI — AI-Native vs AI-Powered; Scaled Agile — What Is AI Native?; Extruct — YC W26 Batch.
Researching Agentic AI (post-April 2026): Built In — Why UX Research Powers Better Agentic AI (April 2026); Akraya — Do Users Trust Your AI Agent? A UX Research Framework for Agentic Experiences (May 2026); Akraya — How to Conduct UX Research for AI Interfaces: A 2026 Guide (May 2026); InfoWorld / Priyanka Kuvalekar (Microsoft) — Building Enterprise Voice AI Agents: A UX Approach (May 2026); Pedro del Rio (Medium) — The Trust Problem: Why Designing for AI Agents is the Hardest UX Challenge of 2026 (April 2026); McKinsey — State of AI Trust in 2026: Shifting to the Agentic Era (March 2026).
Infrastructure & Knowledge Management: Startup GTM (Substack) — Self-Updating AI Knowledge Base; IONOS — Prompt Libraries; BRICS-ECON — Centralized Prompt Libraries; Elvex — AI Integration vs MCP vs API.
Failure Modes & Risks: AI Magicx — Why 80% of AI Projects Fail; CNBC — AI Brain Fry; Fortune — AI Straining Workloads; DX Newsletter — AI Productivity Gains Are 10%, Not 10x; Yale News — AI’s Hidden Bias; UC Berkeley — AI Speech Evaluation Bias.
Other: User Interviews — AI UXR Tools; CTO Magazine — AI Operating Model.
AI Disclosure
I prompted ChatGPT, Claude, and Copilot with the following on April 14th:
I want to create a plan for infrastructure and processes to make my UX research team AI-native. I want you to search the web for all articles published on how UX research teams are moving to be AI-native, especially since December 2025 with the advances in coding models. Also, review what’s been posted about how cross-functional teams and startups are using AI and consider how those practices could be applied to UX research. Review all of the articles you find and synthesize some common patterns as well as highlighting exceptions that only a small group of researchers or teams are doing. Turn these into a plan for our team, that includes infrastructure investments — e.g. a shared repository of research findings — and processes / ways of working — e.g. using agent skills to plan research.
I set each to Deep Research and enabled Web Search Tools. I took all three outputs, combined them, and iterated on them with human reviewers. I chose the structure of the essay and adjusted tone throughout to match my own.
I went through everything and edited it into a first draft. I then asked for a light revision pass with all large changes reviewed by me first:
Please take a look through and iterate on this draft.
Specifically:
Look for places where I’ve added comments and try to address them
Look for duplicative content from combining the Deep Research reports and consolidate
Look for duplicative citations and consolidate
Ensure all claims are linked to their citations
Suggest a conclusion
I’d like it to be shorter, tighter, and practical for readers to be able to try the approaches described in the essay so any suggestions there are appreciated
Look for places of awkward transitions and smooth them out
Make small changes without asking for permission. Check with me on any large restructurings of the essay.
I then made edits and revisions myself as well as getting feedback from a few early reviewers. I then asked Claude to search for articles published after April 14th to update the essay. I finished with an final editing pass on my own.
Thanks Jess for this detailed article. A few things stood out to me.
Regarding AI Native UXR Mindset:
Another wrinkle to becoming more AI native for a UXR is embracing these AI tools and features in general. I’ve seen researchers hesitate to adopt these tools because of prior anchor experiences, skepticism, or fear that AI will replace them. But the researchers most at risk of being replaced aren’t the ones using AI—they’re the ones refusing to incorporate it into their workflow.
Multi-source synthesis on top of a research repo:
I imagine this is where Office365, Google Drive, and other tools could become 10x improvements to help researchers and all knowledge workers. For example with my own research projects using Co-work across my Obsidian vault, which is setup exactly how I would my own Google Drive with the relevant context, files, and other projects all in one place for the agent to review has been a major improvement in my productivity.
Making it social:
Ultimately I believe we will need more UXRs in the world, not less. And part of what will differentiate the super-UXRs I believe is their ability of course to drive decisions. That is always what the job comes back to. Informing and driving decisions that make an impact. This is something that I think gets lost for many researchers. Some might view AI as a way to "speed up research" or "do more research". I am more impressed with the researcher who uses AI to look back at different studies we've conducted to tell the team, "Hey, we already have insights on this topic to make a confident decision. Don't run the research."
AI Moderation Interviews:
I have been a participant for many AI-moderated studies. Most of the time I view them has usability studies with a small incremental improvement. It's just opened ended questions with my brain feeling fried after 10 minutes because I'm talking to a screen that has asked me the same question four different ways. I think they are good for a super narrow, tangible use cases, but for now mostly just something to get quick insights for likely a decision that doesn't have that high of a priority. I could be wrong.
Jess, could you take a look at this repo? https://github.com/dcatalanmolina/minga-insights-vault
I'm working on improving documentation and examples for a wider release. I'd love any feedback/reactions based on all the gems you dropped in the Infrastructure and Green Shoots sections of your article. Here's the first release note just in case: https://companero.substack.com/p/release-note-minga-v010